Research & ML
Bearing Fault Diagnosis with a 1D CNN
A 1D CNN that classifies bearing faults from raw vibration signals (CWRU dataset), tested on an unseen motor load and under added noise, with a Streamlit app for uploading a signal.

Can a small 1D CNN tell a healthy bearing from three kinds of fault using only the raw vibration signal, and how far can it be trusted?
Watch the video demo · Open the app
Setup
- Data: the public Case Western Reserve University (CWRU) bearing dataset, four classes: normal, inner-race fault (IRF), outer-race fault (ORF) and ball fault (BF).
- Windows: each recording is cut into 2,048-sample windows with 50% overlap.
- Split by motor load, not at random: training and validation use the 0 HP and 1 HP recordings; the test set is the 2 HP recordings (824 windows), which the model never sees. A random split would put overlapping windows of the same recording on both sides and inflate the score.
- Imbalance: normal windows outnumber each fault class about four to one. Two models were trained for 25 epochs each: one on the original data, one on data balanced with SMOTE.
- Model: three Conv1d + BatchNorm + pooling blocks and a small classifier, in PyTorch.
Results
| Test (2 HP, 824 windows) | Accuracy |
|---|---|
| Original data | 100% |
| SMOTE-balanced data | 100% |
| + noise at 25% of signal std | 100% |
| + noise at 50% | 87.0% |
| + noise at 75% | 28.8% |
| + noise at 100% | 23.7% |
What the numbers actually say
- CWRU is easy for a CNN. Both models were perfect on the unseen load, so this test cannot show whether SMOTE helps. A harder dataset, or a test on different bearings, would.
- Noise is where it breaks. At 50% noise, ball faults are mostly mistaken for inner-race faults (BF recall 9%). At 75%, almost everything is called an inner-race fault. A real sensor in a noisy plant would need noise augmentation in training, or denoising before the model.
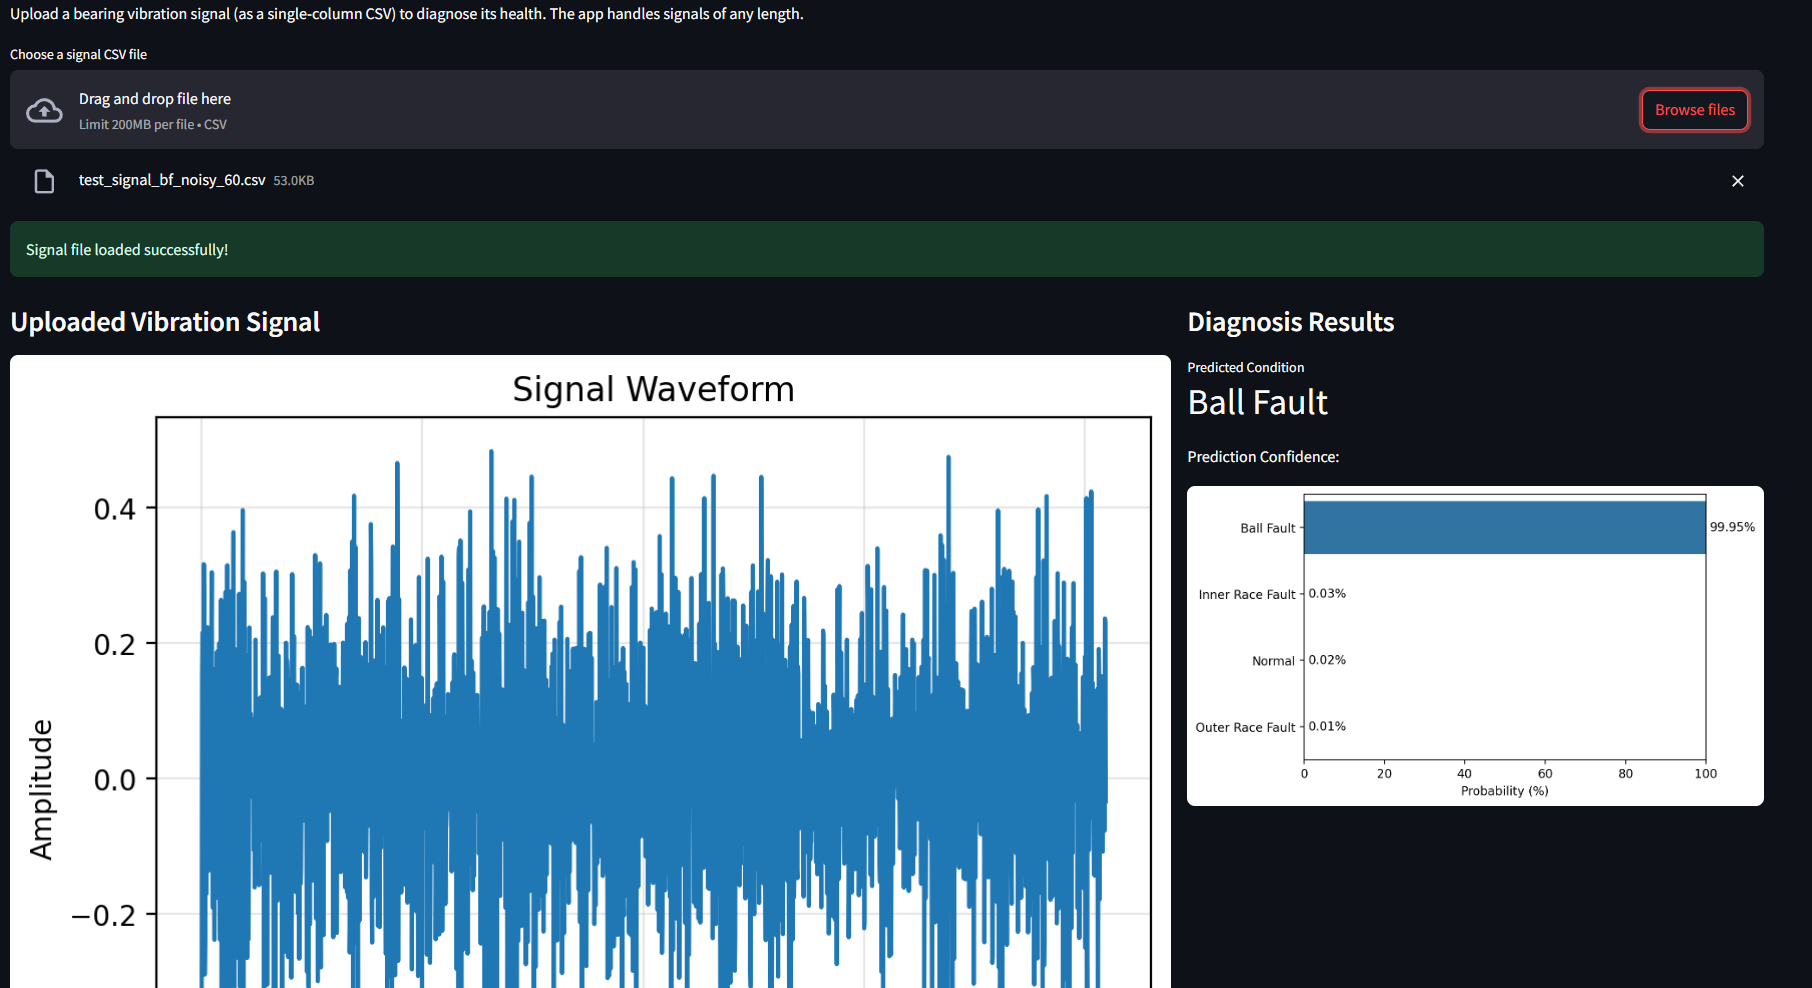
- The app handles real-length signals. Inputs shorter than a window are extended by reflection padding; longer ones are cut into overlapping windows, and the class probabilities are averaged across them.
Built with
Python, PyTorch, scikit-learn and imbalanced-learn (scaling, SMOTE), pandas and NumPy, and Streamlit for the app. The four notebooks go from data exploration to the trained model and the app.