Research & ML
Distill-SSL
Self-Supervised Teachers, Small Students
A 25-experiment study on STL-10: pretrain ResNet-18 teachers with SimCLR, BYOL, and DINO, then distill them into a MobileNetV3-Small student with single, ensemble, and progressive strategies.
- Type
- Research & ML
- Date
- November 18, 2025
- Status
- Completed
- Stack
- Deep LearningSelf-Supervised LearningKnowledge Distillation
- Links
- Source
Can a small model learn from large self-supervised teachers, using only a few labels?
A course project for CHE 567 (AI in Chemical Engineering) at KFUPM. Full code, logs, and the experiment runner are on GitHub.
Setup
- Data: STL-10, with 100,000 unlabeled images for self-supervised pretraining, 5,000 labeled images for fine-tuning and distillation, and 8,000 test images.
- Teachers: four ResNet-18 models: three pretrained with SimCLR, BYOL, and DINO, then fine-tuned; one trained supervised from scratch as a baseline.
- Student: MobileNetV3-Small, distilled with:
- a single teacher,
- an ensemble of two or three teachers,
- progressive distillation, where the student learns from one teacher after another.
- Runner: one script runs all 25 experiments, then measures model size and FLOPs and builds the plots and summary table.
Results
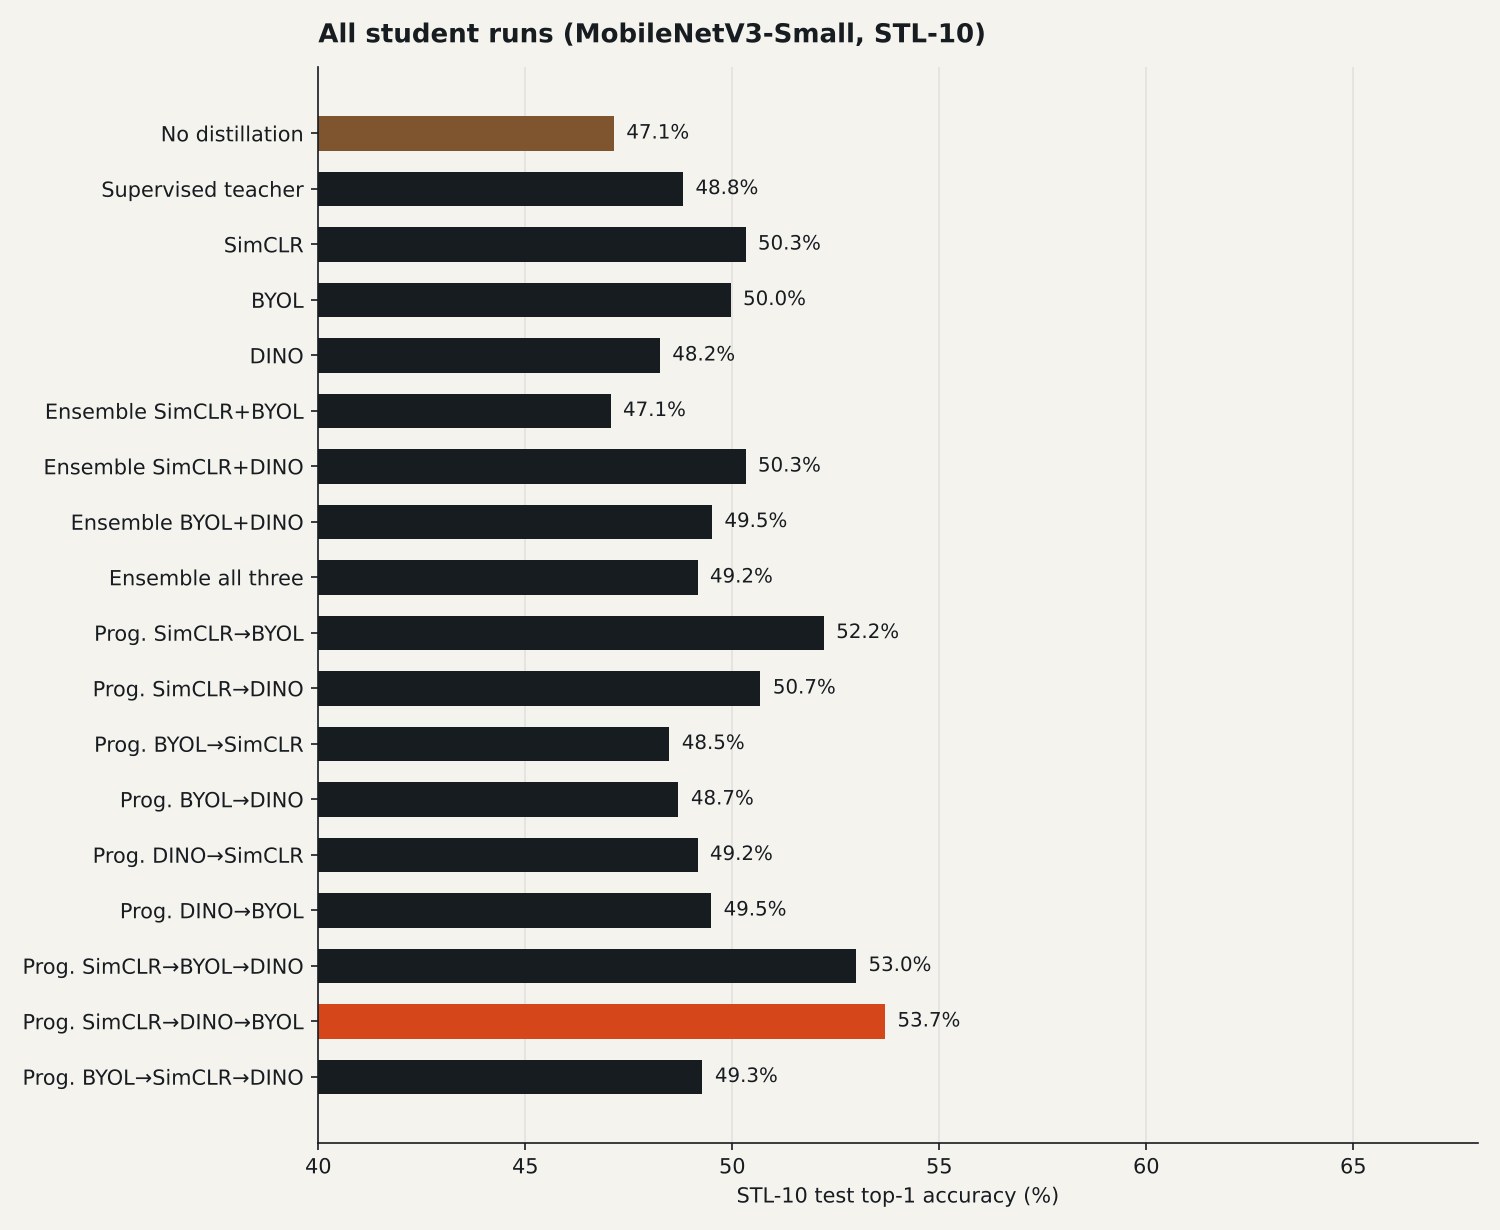
- The student trained alone reached 47.1% top-1 accuracy.
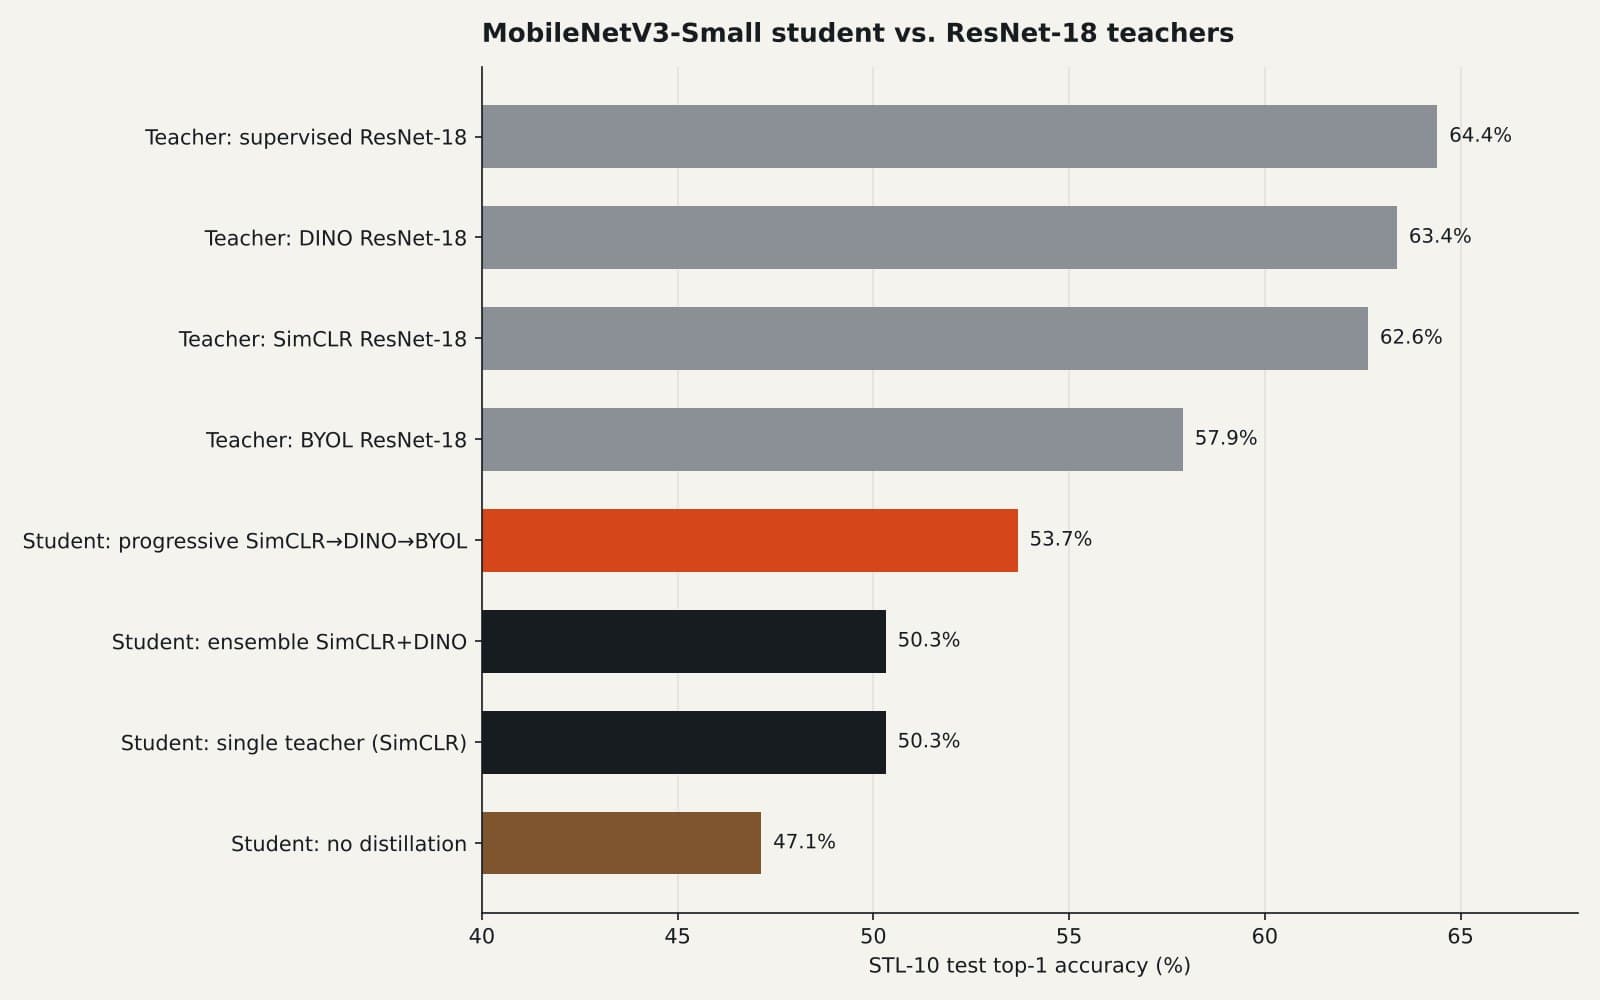
- The best distilled student (progressive, SimCLR → DINO → BYOL) reached 53.7%, a gain of 6.6 points.
- Teachers ranged from 57.9% (BYOL) to 64.4% (supervised).
What the numbers actually say
- Distillation helped. Every progressive and most ensemble students beat the student trained alone.
- Self-supervised teachers did not beat the supervised one here. With only 5,000 labels and short pretraining, the supervised ResNet-18 was the strongest teacher. Better pretraining budgets would likely change this, but this study does not show it.
- Progressive students also trained longer. Each extra stage added 30 epochs, so part of their advantage may come from the additional training, not only from the order of teachers. A fair follow-up would match total epochs.
- The gap to the teachers stays large (about 10 points), which is expected for a student this small at this data scale.